Resilience is not an accident; it is engineered. At Plotkai Interactive, we specialize in high-availability Site Reliability Engineering (SRE), merging advanced 99.999% uptime designs, AI incident routing, Model Context Protocol (MCP) diagnostics, self-healing systems, and multi-region disaster recovery blueprints to guarantee your product stays online under extreme scales.
Our SRE Engineering Pillars & Expertise
Explore how we fuse human governance, AI-driven automation, and deep failover structures to secure total availability.
99.999% SLA Availability
Eliminate single points of failure. We construct active-active application meshes, calculate strict error budgets, and govern SLOs/SLIs to deliver five-nines operational reliability.
- ✔ Standardizing 99.999% SLA thresholds across core infrastructure
- ✔ Strict calculation and alerting on operational error budgets
- ✔ Automated high-availability (HA) configuration audits
Kanban Visual Incident Management
Bring strict visualization to operational streams. We coordinate incident backlogs and live ticket cycles using SRE Kanban structures that suppress bottleneck build-ups.
- ✔ Incident flow tracking boards reducing Mean Time to Detect (MTTD)
- ✔ Visual backlog prioritization to eradicate repetitive toil
- ✔ Continuous throughput optimization avoiding resource exhaustion
Real-Time Monitoring (RTM)
Observe response times continuously. We establish real-time response time monitoring (RTM) pipelines that evaluate request delays, network speed fluctuations, and traffic bursts.
- ✔ Continuous RTM tracking loops for active transaction latency auditing
- ✔ End-to-end response time monitoring correlating network and system speeds
- ✔ Live synthetic performance charts providing instant latency degradation alerts
AI incident Routing & Dispatch
Expedite triage speed under pressure. We implement AI intelligence models to automatically classify incoming log anomalies, drop duplicate alerts, and dispatch page loops.
- ✔ AI-driven log classification categorizing incident types instantly
- ✔ Intelligent incident ticket routing dispatching pages to dedicated cohorts
- ✔ Automatic alert correlation suppressing up to 90% of alert noise
MCP-Powered First-Stage Debugging
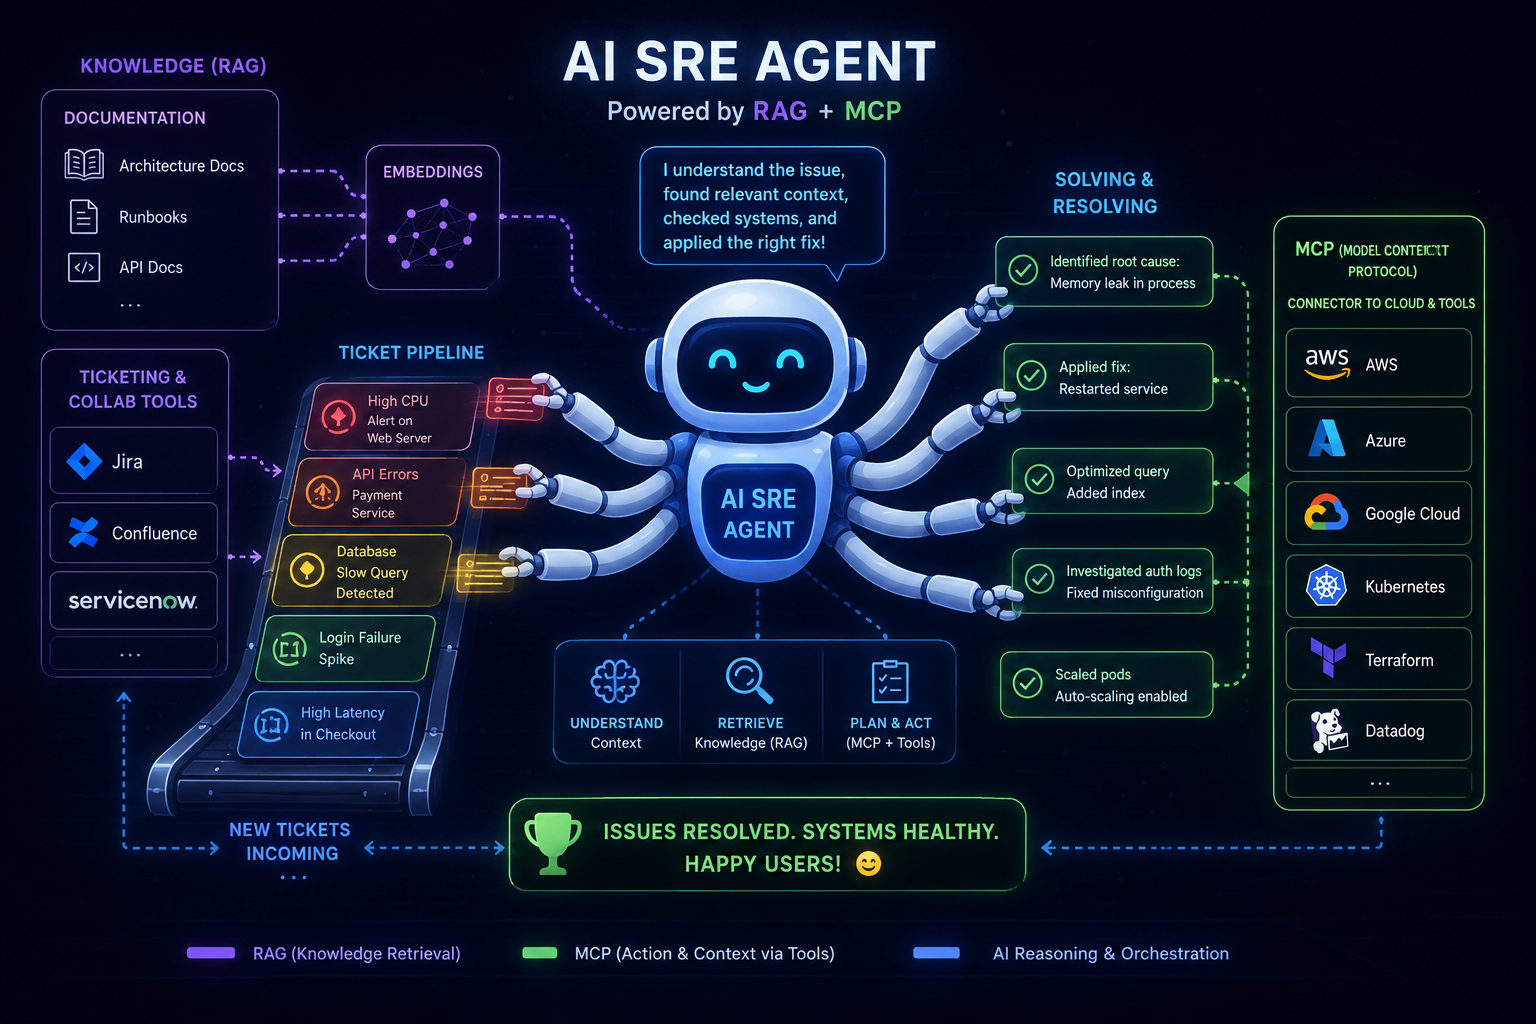
Automate the first 10 minutes of operational troubleshooting. We configure Model Context Protocol (MCP) agents that fetch container stats, review logs, and draft diagnostics.
- ✔ First-stage diagnostic gatherers powered by Model Context Protocol (MCP)
- ✔ Automated retrieval of server stacks and recent container log cycles
- ✔ LLM-assisted remediation proposals generated during incident creation
Metric Alerts & PagerDuty Integration
Establish strict escalation loops using live metrics. We build Prometheus and Datadog metric-alert pipelines that bridge critical faults straight to developer pagers.
- ✔ High-reliability metric alerts routed dynamically via **PagerDuty**
- ✔ Robust, multi-level shift escalations guaranteeing 24/7 coverage
- ✔ Direct integration with live system health dashboard panels
Self-Healing & Auto-Remediation
Let software remediate software failures. We develop secure, autonomous auto-healing scripts that resolve resource lockouts and container faults automatically.
- ✔ Event-driven auto-remediation loops resolving pod lockouts
- ✔ Automated circuit breaker resets and memory leak dump sequences
- ✔ Secure runtime isolation preventing auto-remediation loops
Multi-Region Disaster Recovery
Establish secure, fail-proof regional fallback architectures. We setup active-active multi-region database replications and design DNS routing systems.
- ✔ Multi-region active-active databases (Aurora Global Database, DynamoDB Global Tables)
- ✔ Rapid automated DNS failover setups using AWS Route 53 routing health policies
- ✔ Periodic automated disaster recovery simulation runs (Chaos Mesh, LitmusChaos)
Proven Operational SRE Impact
Metrics achieved through our high-availability and self-healing SRE integrations.
Our SRE Hardening Roadmap
How we align your SRE processes and runbooks from auditing to self-healing.
1. SLA Baselining & Visual Governance
We configure SRE Kanban incident boards, outline system limits, define target SLOs/SLIs, and calculate error budgets.
2. Telemetry, RTM & AI Pager Routing
We implement response time monitoring (RTM), configure Prometheus alerting, and deploy AI incident classifiers to feed correct PagerDuty shift schedules.
3. MCP Debugging & Auto-Remediation Loops
We deploy LLM-powered MCP diagnostic nodes to fetch server stats instantly, and configure automated auto-healing scripts for isolated self-repair.
4. Chaos Engineering & Multi-Region DR Auditing
We run automated chaos engineering drills (Chaos Mesh), test active-passive DNS routing limits, and guarantee zero-downtime database failovers.
Sustain Massive Scale Confidently
Is your engineering team plagued by frequent downtime, long MTTR, alert fatigue, or lack of solid disaster recovery simulations? Let our team of seasoned SRE and cloud architects perform a comprehensive Free SRE & Reliability Audit.