In the modern cognitive era, AI is no longer a simple chatbot interface—it is the central nervous system of competitive startups. At Plotkai Interactive, we design production-grade, secure, and cost-optimized Artificial Intelligence and Machine Learning systems engineered to drive autonomous decisions, massive operational efficiency, and state-of-the-art user experiences.
Our AI/ML Pillars & Expertise
Explore the full spectrum of cognitive and predictive capabilities we design, deploy, and manage.
GenAI & LLM Orchestration
Harness state-of-the-art Generative AI capabilities. We orchestrate Foundation Models, customize proprietary LLMs, and optimize context efficiency.
- ✔ Multi-LLM workflows & routing frameworks (Gemini, Claude, GPT)
- ✔ Custom parameter-efficient fine-tuning (LoRA, QLoRA)
- ✔ Semantic context window optimization and prompt compression
Data Engineering & Cleaning
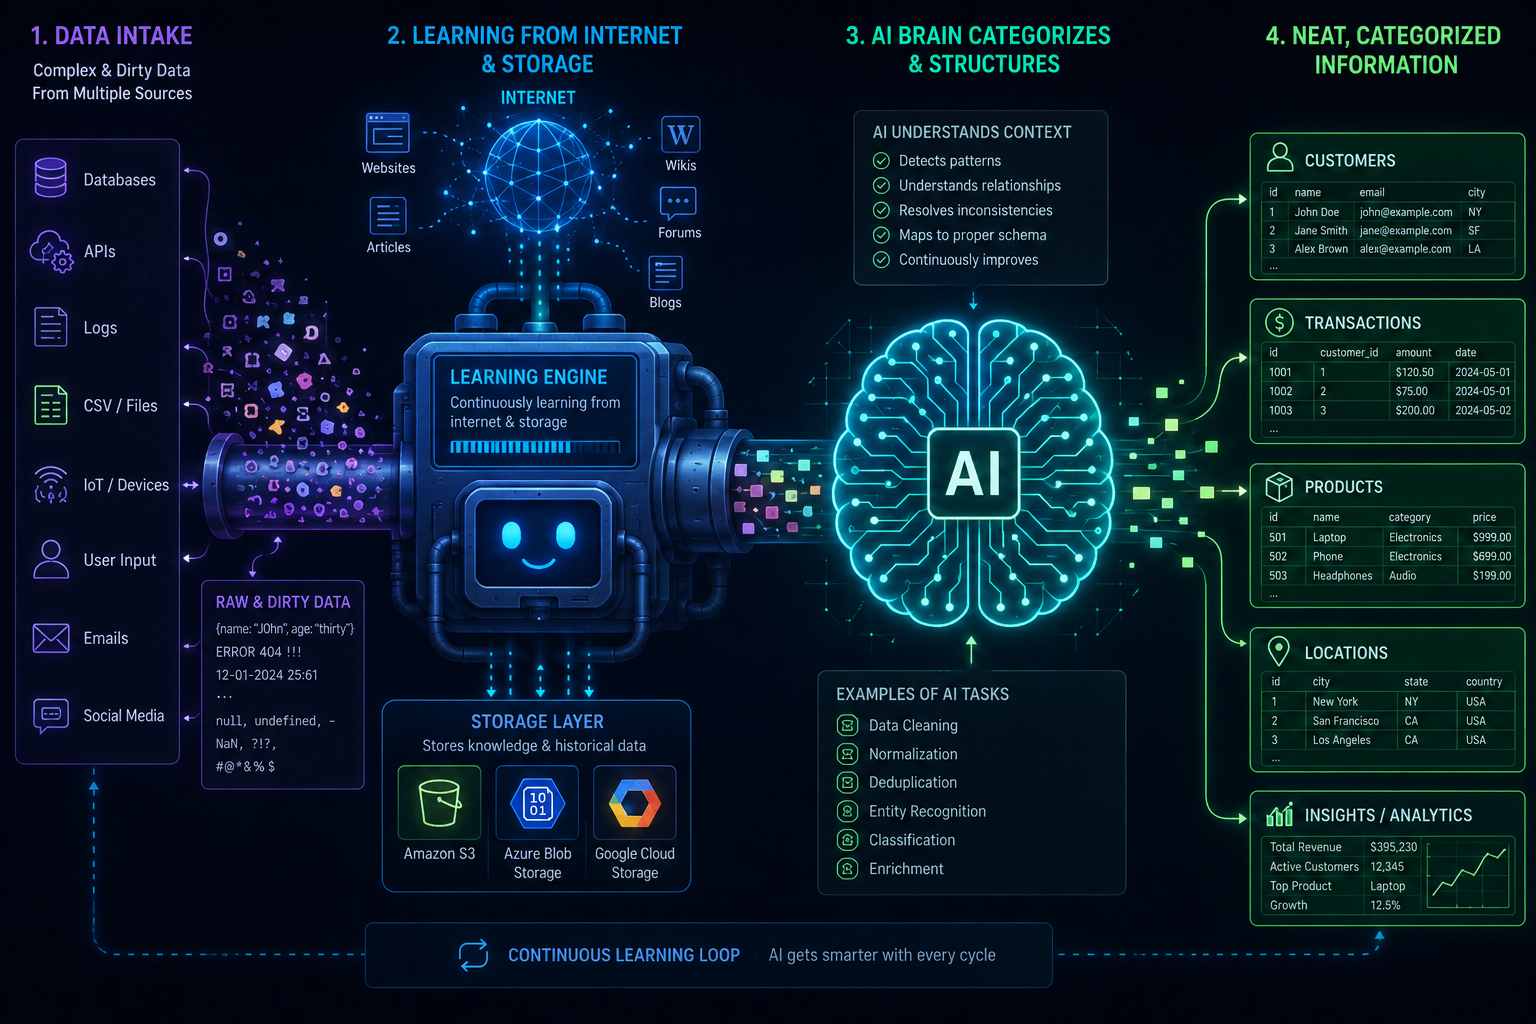
High-performing AI starts with pristine data. We build distributed ingestion pipelines that clean, deduplicate, and prepare text, logs, and rich media.
- ✔ Distributed data ingestion and ETL (Apache Spark, dbt, Ray)
- ✔ Automated outlier removal, null-value imputations, and deduplication
- ✔ Structured datasets construction for pre-training and fine-tuning
Data Governance & Security
Establish strict enterprise data policies. We ensure customer data is protected, compartmentalized, and never leaked during model tuning.
- ✔ Granular access controls, tokenization, and PII anonymization
- ✔ Full data lineage mapping and model training isolation guarantees
- ✔ SOC2, HIPAA, and GDPR compliance validation across model endpoints
Guardrails & Trustworthy AI
Secure your AI interface against threat vectors. We deploy safety layers, audit outputs, and immunize systems against bad prompt engineering.
- ✔ Real-time prompt injection & jailbreak prevention (NeMo Guardrails, Llama Guard)
- ✔ Output validation to suppress hallucinations and toxic generations
- ✔ Hallucination scores, factuality checkers, and latency budgets mapping
Model Training & MLOps
Orchestrate machine learning pipelines at scale. We automate training, deploy robust MLOps, and configure cost-efficient compute orchestrators.
- ✔ Scalable training & tuning pipelines (Kubeflow, MLflow, Ray Train)
- ✔ Model registry, lineage tracking, and hyperparameter logs
- ✔ Managed GPU scaling (AWS SageMaker, GCP Vertex AI, Kubernetes autoscalers)
Vector Search & Embeddings
Convert unstructured logs, documents, and interactions into deep search capabilities. We build blazing-fast semantic storage architectures.
- ✔ Vector database integration (Pinecone, pgvector, Qdrant, Milvus)
- ✔ Real-time chunking, metadata filtering, and semantic embeddings pipelines
- ✔ Hybrid search configurations combining keyword (BM25) and dense vectors
Human-in-the-Loop Reinforcement
Ensure absolute precision through combined human-machine feedback loops. We build RLHF pipelines and custom active learning user workspaces.
- ✔ RLHF (Reinforcement Learning from Human Feedback) orchestrations
- ✔ Human verification gates for low-confidence predictive model outputs
- ✔ Active learning cycles to dynamically feed labeled samples back to training
Agentic Workflows & MCP
Construct highly cooperative multi-agent environments. We implement Model Context Protocol (MCP) servers, tool-use loops, and self-reflecting loops.
- ✔ Model Context Protocol (MCP) server design for standard tool-use integration
- ✔ Autonomous multi-agent routing engines (LangGraph, CrewAI)
- ✔ Self-healing agent execution blocks equipped with sandboxed tool sandboxes
Proven AI Performance Metrics
Metrics tracked across our state-of-the-art production installations.
Our AI Implementation Roadmap
How we move your models from baseline concepts to production velocity.
1. Data Prep & Lineage Discovery
We map your datasets, evaluate quality constraints, configure cleaning pipelines, audit PII liabilities, and trace initial data lineage streams.
2. Model Feasibility & Embedding Mapping
We test baseline models, establish vector index sizes, design dense prompt schemas, and outline hybrid keyword-semantic search architectures.
3. Distributed Fine-Tuning & MLOps Setup
Using Kubeflow and MLflow pipelines, we orchestrate parallel GPU training, track weights, configure active model registers, and deploy validation benchmarks.
4. Guardrails Hardening & Human-in-the-Loop (HITL)
We deploy real-time safety guardrails (Llama Guard/NeMo), configure human feedback review gates (RLHF), and scale low-latency endpoint serving engines.
Let's Design Your AI Advantage
Is your startup facing soaring API costs, uncalibrated model outputs, raw data bottlenecks, or fragile prompt security? Let our team of certified MLOps and GenAI platform architects perform a comprehensive Free AI & Data Architecture Audit.